Opus 5.5 vs Sonnet 5.5 vs Fable 5.1Names hidden. Which is which?
Three Claude models made the same doodled mini-golf game. Putt through each one.
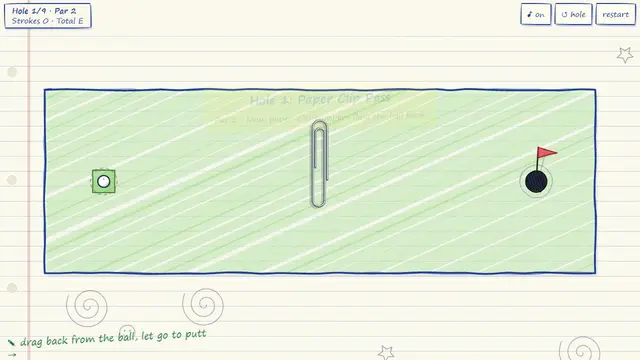 works · try 1 of 2AnthropicOpus 5.5 · HighOpen Opus 5.5 · High
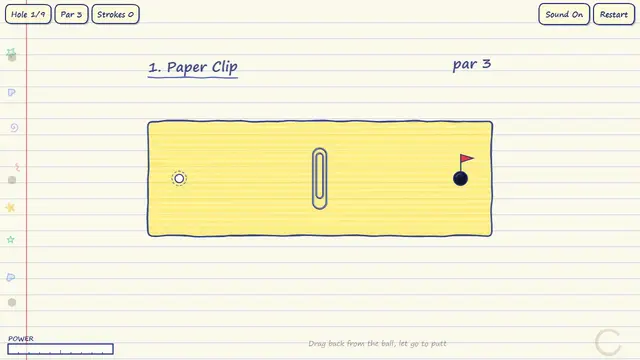 works · try 1 of 2AnthropicSonnet 5.5 · HighOpen Sonnet 5.5 · High
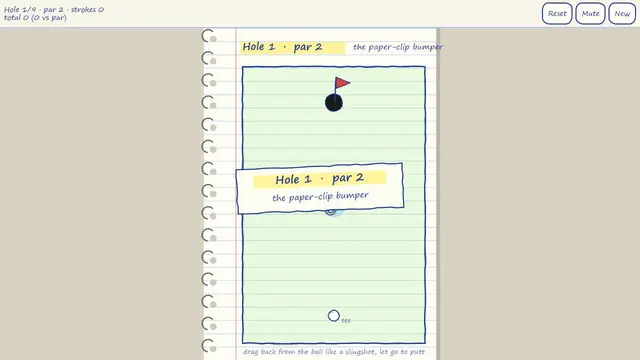 works · try 1 of 2AnthropicFable 5.1 · HighOpen Fable 5.1 · High
Is it fair?
A fair match: same effort, same kind of tool.
- Same effort
- Agents only
All three ran at high effort as Claude Code subagents, with the same prompt pasted as is. A workflow restart ran this prompt twice, so each run has 2 tries on record; the first try worked every time and is the one shown.
What these mean
- Same effort
- Every run used the same step on the shared effort ladder.
- Agents only
- All runs used coding agents.
Each run
- AnthropicOpus 5.5Effort: High, level 3 of 5works · try 1 of 2Receipt and tries
- AnthropicSonnet 5.5Effort: High, level 3 of 5works · try 1 of 2Receipt and tries
- AnthropicFable 5.1Effort: High, level 3 of 5works · try 1 of 2Receipt and tries
The benchmark
Nine holes of slingshot mini-golf doodled on notebook paper.
Try this: Drag back from the ball like a slingshot, let go.
I keep the exact prompts private for now. See it in the gallery.
Make your own comparison