Opus 5.5 effort ladderNames hidden. Which is which?
One model, five effort levels, the same pelican prompt.
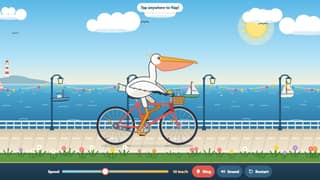
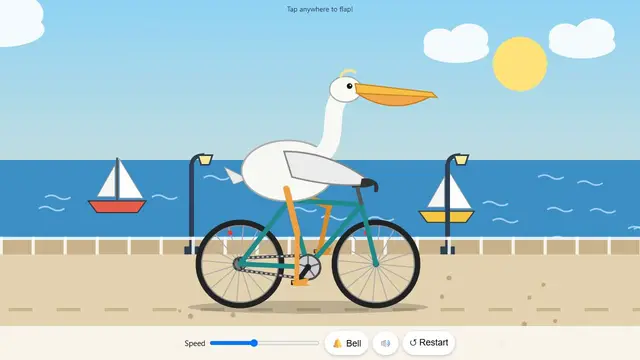 works · try 1 of 2AnthropicOpus 5.5 · LowOpen Opus 5.5 · Low
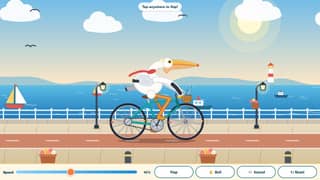
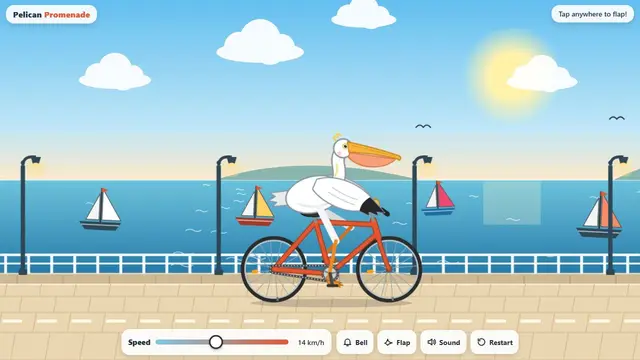 works · try 1 of 2AnthropicOpus 5.5 · MediumOpen Opus 5.5 · Medium
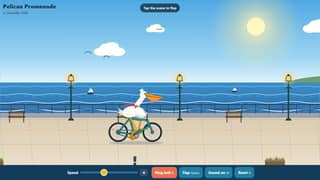
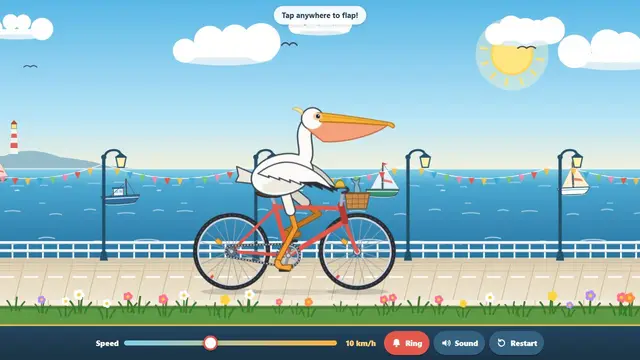 works · 1 tryAnthropicOpus 5.5 · HighOpen Opus 5.5 · High
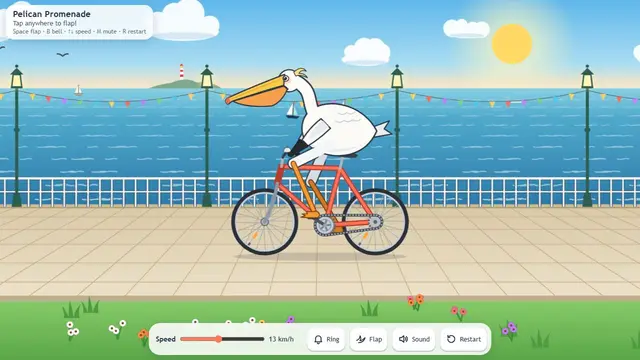 works · 1 tryAnthropicOpus 5.5 · Extra highOpen Opus 5.5 · Extra high
- It thought for 49 minutes and never wrote the file.no fileAnthropicOpus 5.5 · MaxOpen Opus 5.5 · Max
Is it fair?
One AI at different effort levels.
More thinking is not always better: at max effort it never wrote the file, in 2 tries.
- Different effort
- Agents only
- Has failed tries
Same model, different effort on purpose: low, medium, high, xhigh and max. Medium worked on try 1 and broke on try 2, so try 1 is the one shown. Max never wrote a file in 2 tries: each time it hit the output limit twice (a session limit cut the first try; the second was stopped by hand). Low also has 2 tries on record (both work); high and xhigh have one each.
What these mean
- Different effort
- The runs used different effort steps.
- Agents only
- All runs used coding agents.
- Has failed tries
- At least one run did not produce a working demo. Failures stay on the record.
Each run
- AnthropicOpus 5.5Effort: Low, level 1 of 5works · try 1 of 2Receipt and tries
- AnthropicOpus 5.5Effort: Medium, level 2 of 5works · try 1 of 2Receipt and tries
- AnthropicOpus 5.5Effort: High, level 3 of 5works · 1 tryReceipt and tries
- AnthropicOpus 5.5Effort: Extra high, level 4 of 5works · 1 tryReceipt and tries
- AnthropicOpus 5.5Effort: Max, level 5 of 5no fileReceipt and tries
The benchmark
The classic: an animated SVG pelican pedaling a bicycle that really works.
Try this: Ring the bell, then drag the speed slider.
I keep the exact prompts private for now. See it in the gallery.
Make your own comparison